Turning complex business operations into intelligent systems
I help businesses identify high-value opportunities for AI, design practical automation strategies, and build production systems that improve operations, increase revenue, and reduce cost.
From the first process review to a working, measurable system in production.
Nadia Shiroglazova Applied AI & production systems
How the systems I build actually work
Every system on this page closes the same loop: it observes, decides, acts, measures the result, and corrects itself.
Approach
Useful, not impressive
I work at the intersection of technology and operations: understanding how a business works today, finding where intelligence or automation creates leverage, and designing systems that are practical, measurable, and connected to real workflows.
I don't build AI for the sake of having an AI feature. I focus on systems that reduce manual work, improve decisions, create qualified demand, increase operational capacity, or unlock new revenue — and I stay responsible for them through discovery, architecture, build, integration, evaluation, launch, and continuous improvement.
Background
Based
Chicago, IllinoisWorking remotely worldwide
Education
MS Data Science, NorthwesternBS Data Science, Northeastern
Previously
Boston Consulting Group · BainEnterprise data platform and AI tooling teams
Practice
100+ AI/ML projects and initiativesFrom rapid prototypes to production systems
What I do
Six places AI earns its keep
Engagements usually start with the first one and grow into the others.
AI opportunity assessment & automation strategy
Review sales, operations, support, and back-office processes
Find bottlenecks, repetitive work, and quality gaps
Prioritize by impact, feasibility, data readiness, and effort
Define target operating model, architecture, roadmap, and success metrics
Sales & agency automation
Lead generation and prospect discovery
AI-assisted and autonomous outreach
Voice-based qualification and follow-up
CRM updates, lead scoring, routing, pipeline visibility
Response classification and next-best-action workflows
Agentic & voice AI
Production voice agents for inbound and outbound work
Multi-step agents with tools, memory, and business context
Human handoff and escalation design
Conversation quality, latency, reliability, and cost optimization
Predictive decision systems
Risk scoring and prioritization
Predictive calling and capacity optimization
Ranking systems and work queues
Operational forecasting and resource allocation
Interfaces that connect model output to real action
AI evaluation, quality & operations
LLM and agent evaluation pipelines
Human-in-the-loop review systems
Speech and operator-performance analysis
Monitoring, error analysis, and feedback loops
Production AI engineering
LLM, RAG, OCR, and vision-language systems
Data pipelines and model-serving workflows
Integrations with telephony, CRM, APIs, and internal tools
Self-hosted and cloud AI infrastructure
Selected work
Systems in production
Open any project to see how it is built.
Also built
Bots
Telegram commerce bots with card and crypto payments
Online shops and service businesses
Bots that take payments, top up in-bot wallets, track balances, and send transaction notifications, with intent recognition routing each request to the right tool. Card payments ran through established providers. The hardest part was the crypto payment integration.
10,000+
calls processed daily
~92%
accuracy on disposition validation
20% → 100%
monitoring coverage
~50%
lower monitoring headcount
Transcription, status detection, and LLM evaluation of every call against 10+ operator KPIs — script adherence, objection handling, empathy, upsell technique, resolution quality. Disputed cases go to a human arbitration loop whose decisions feed back as training signal, which lifted accuracy a further 15%. Migrating from a third-party LLM API to a self-hosted 70B model cut running costs roughly in half at the same throughput.
Fixed dialing settings are a bad trade: dial fast and callers wait on hold, dial slowly and operators sit idle. This controller solves the allocation on a rolling horizon instead, modeling transfer delay as an empirical lag convolution and validating through discrete-event simulation calibrated to production data. Results shown are from counterfactual replay against the previous policy. The method is published.
Prospecting runs without a human in it: the system discovers businesses through the Places API, classifies them by category and fit, calls to qualify, then ranks by warmth from engagement signals and sends a personalized follow-up. Full call history is retained, so a prospect who calls back is resumed in context rather than re-introduced cold.
Google Places APIAI voice qualificationLead warmth scoringResponse classificationCRM integration
5
horizon-specific models replacing one static one
Daily
operational re-prioritization
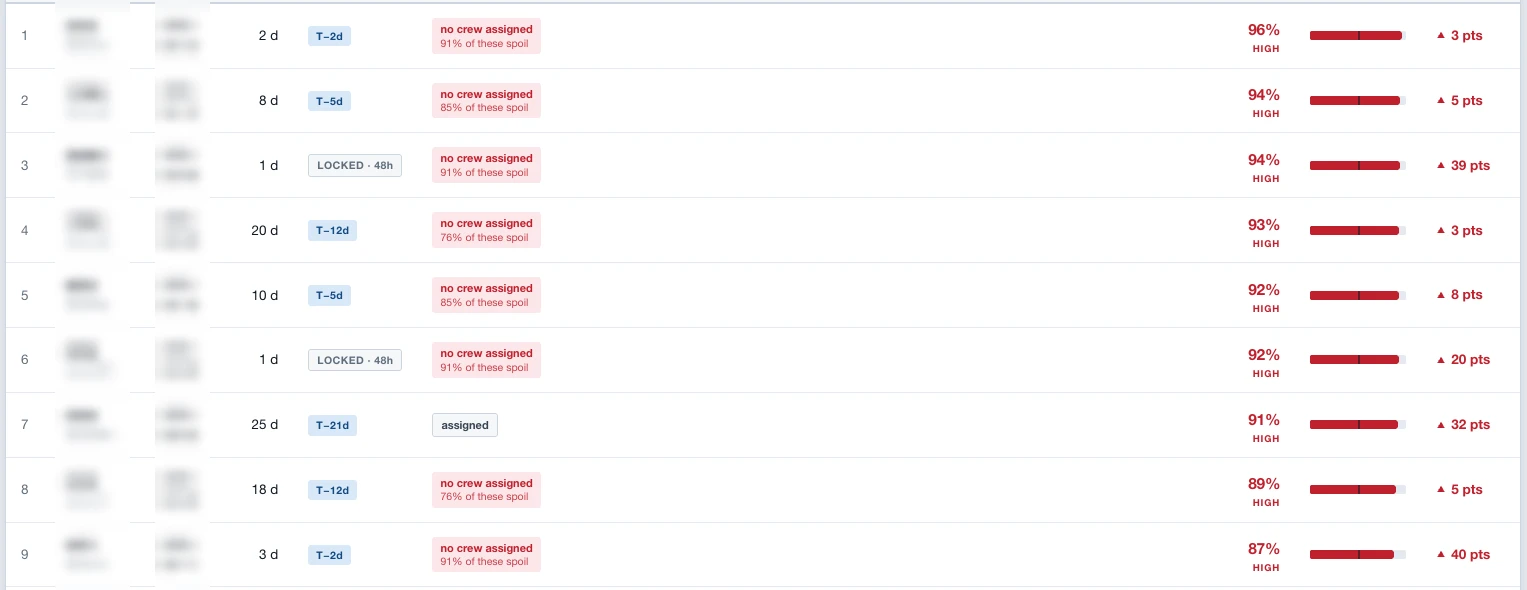
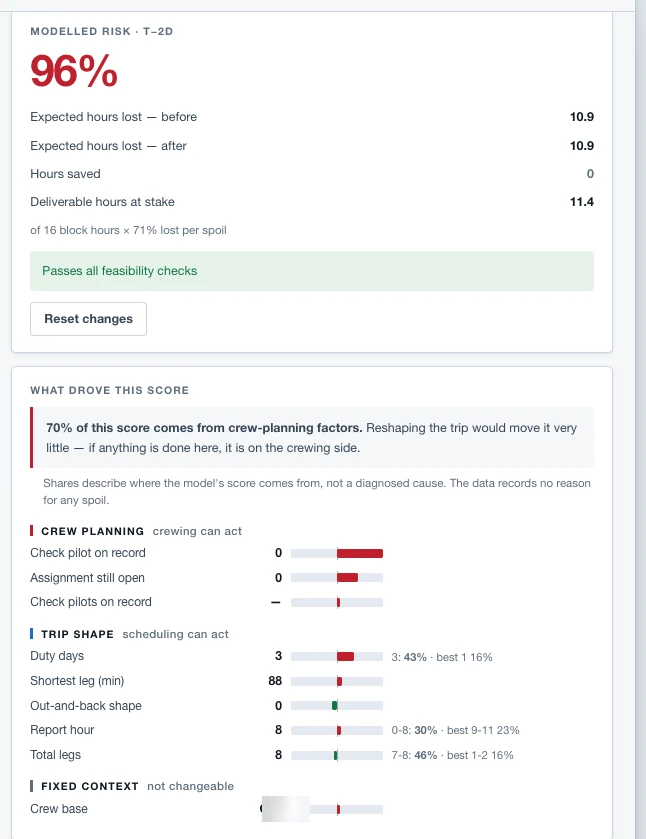
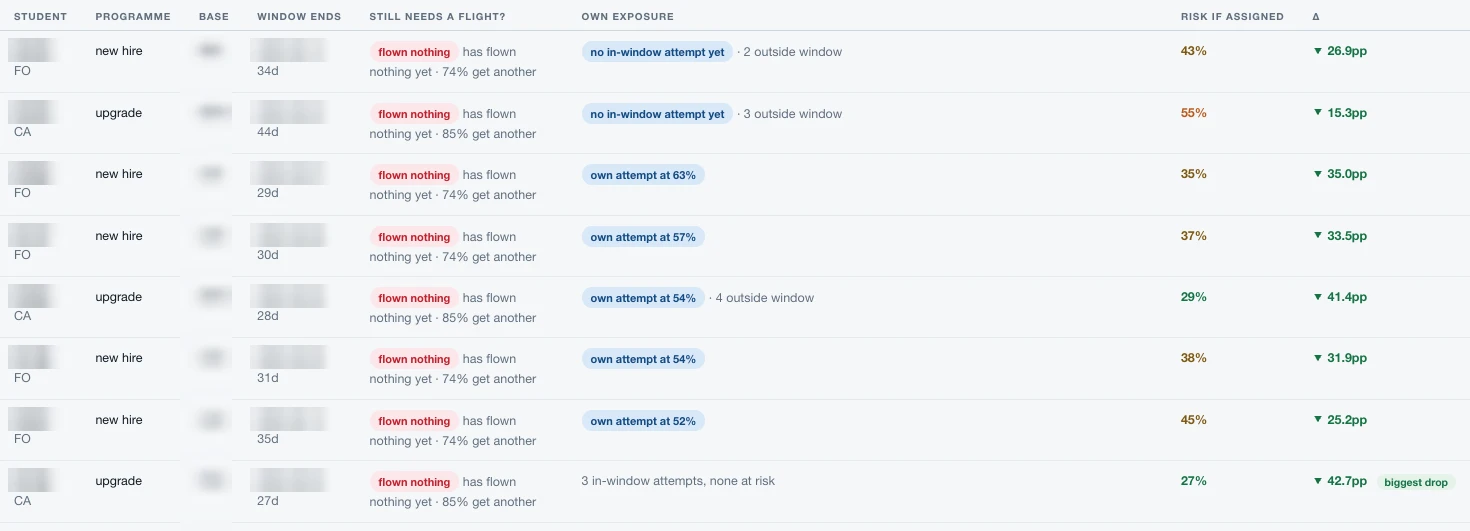
A single static risk score can't tell a coordinator what to do this morning. This system runs five horizon-specific models over point-in-time features — using only what was knowable at each decision point — then surfaces the highest-risk training sequences and ranks candidate students for recovery by availability, prior disruption, training need, and current risk. Validated chronologically, with historical replay and what-if analysis built into the coordinator workflow.
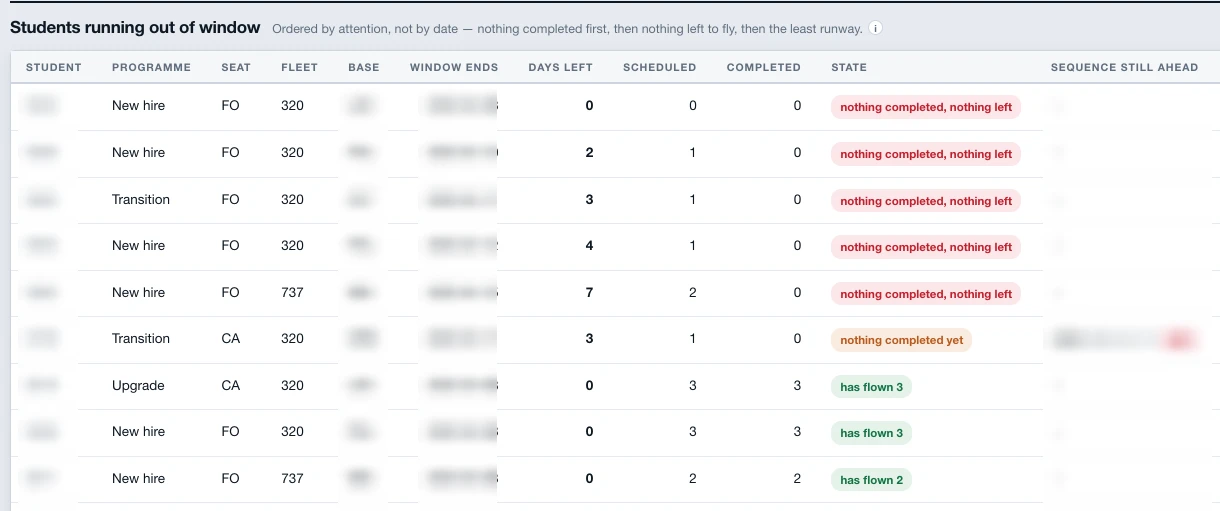
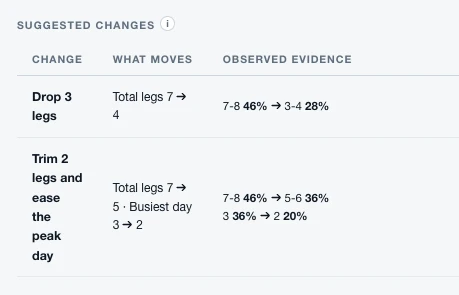
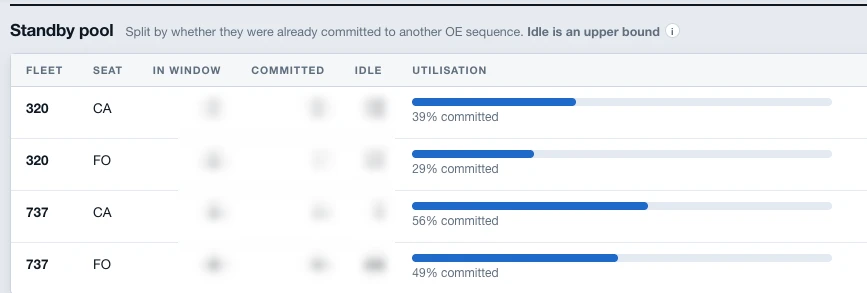
The coordinator tool is built around the decisions people actually make. Upcoming sequences are ranked by modeled risk, with the main driver flagged. Each score breaks down into what drove it, split into factors crewing can act on, factors scheduling can act on, and fixed context, so it's clear who should act. The tool suggests schedule changes backed by observed evidence, shows a pool of candidate students who could fill an at-risk sequence along with the risk if each is assigned, tracks students running out of their training window, and shows standby capacity by fleet and seat. Identifiers and operational details in the screenshots are hidden.
Upcoming sequences ranked by modeled risk, with the main driver flaggedWhat drove a score, split by who can act on itCandidate students to fill an at-risk sequence, with risk if assignedStudents running out of their training window, ordered by urgencySuggested schedule changes, each backed by observed evidenceStandby capacity by fleet and seat
Documents are classified and routed by a vision-language model with OCR fallback, then answered through a hierarchical RAG pipeline with sentence-level citation and recursive three-level summarization. The entire stack was migrated off third-party APIs to self-hosted deployment to satisfy the client's data-residency and confidentiality requirements.
delivery rate on problematic addresses, depending on country
~96%
validation accuracy
15+
countries across Europe and Latin America
There is no single source of truth for addresses across 15+ countries. Each country has its own authoritative providers alongside Google Places, and each region and city carries its own formatting conventions and validity rules — so the system holds a per-country source set and a regional rule set rather than one global model.
Disagreements between sources are surfaced with plain-language reasoning instead of a bare confidence score, so a reviewer can spot-check in seconds. The most useful part is the loop: the LLM acting as judge proposes changes to the rules themselves when it sees a pattern the current rules mishandle, and a human confirms or rejects them. The rule set improves per region without anyone rewriting it by hand.
lower cost per sale than at launch, reaching the business target
670–990 ms
response latency
<1%
of customers realized they were talking to AI
~60%
lower cost per contact than human operators
In a cold call, a pause kills the conversation, so latency was the main design constraint. The agent speaks Spanish and a range of other European languages, including Bulgarian and Slovak, which needed the most work. The first version ran as a single sequential process. I rebuilt it as a multi-threaded graph of small nodes and edges, splitting each stage into small blocks so the agent can move between them quickly. Speech and language models are called through APIs chosen for the best speed-to-quality balance, and the agent responds in 670–990 ms.
Handoff is queue-aware. While talking, the agent makes a tool call to check whether an operator is free. If no one is, it keeps the conversation going. As soon as someone frees up, it transfers the call and writes a context card to the CRM, so the operator picks up mid-conversation and doesn't have to start over. The rollout started with a low-priority customer segment and was measured against human operators: conversion matched, and engaged customers stayed on the line for 8–10 minutes, the same as with people. The agent only costs money during live conversations, since voicemail and no-answers are free. Iterating on that, we brought cost per sale down to the target the business set, four times lower than at launch.
A/B rollout against operators, then full handover by country
0
jobs cut: operators moved from confirmation to sales
The agent covers next-day delivery confirmation, pickup reminders, and failed-delivery follow-ups. In some countries it can also reschedule a delivery or change the address. It isn't one bot copied across markets: each country gets its own configuration of tools, context, and behavior, and some markets went through additional voice testing before launch.
The rollout ran as a 50/50 A/B test against human operators in each country. Where the results held, the agent took over 100% of the workflow, and operators there no longer handle confirmations. No one was let go: the team now spends its time on sales, where people add more value than they do confirming deliveries. High-value orders get extra care. They are routed to a more capable LLM, and critical cases are transferred to an operator.
Multilingual voice AIPer-country configurationTool callingValue-based model routingA/B rolloutVoice testingHuman escalation
+5%
revenue uplift after rolling out the changes
25+
speech and structural metrics per operator
43
operators across two call centers
0.84
gap in the same metric's correlation with profit between the two centers
Every call is transcribed and scored by an LLM against a stage-based rubric: opening, needs discovery, presentation, price, objections, and close. On top of the content score, the system computes 25+ speech and structural metrics per call, aggregates them per operator, and correlates each one with that operator's profit. It runs on the pooled sample and on each call center separately.
The most useful finding came from that split. Both centers sell the same products to the same countries, yet objection-handling quality correlated with profit at r = +0.54 in Europe and r = −0.30 in Latin America. Good handling doesn't hurt sales. In the second center, a high objection count mostly signals a low-intent customer whom even a flawless response won't convert. So a scoring rubric calibrated on one center can't be copied to another, and the weights are now set per center.
The findings went straight into operations: updated scripts and operator training, sharper AI feedback for supervisors, and a reworked QA report. Some "errors" that turned out not to matter are no longer penalized, some were dropped, and criteria that do matter were added. The method is published.
Keyword search misses candidates who describe the same skill in different words, and rewards those who simply repeat the right terms. Here every resume and job posting is indexed in Qdrant twice: as a sparse vector that catches exact terms like tools, titles, and certifications, and as dense embeddings that capture meaning. The two rankings are merged with standard rank fusion, and custom feature extraction adds structured signals from both sides.
On top of retrieval sits a weighted scoring layer that recruiters control. Toggles in the interface set how much location proximity, years of experience, skills overlap, and domain background matter, and the ranking updates immediately. A senior niche role and a high-volume hire need different trade-offs, and recruiters can set them per vacancy without retraining anything. On internal evaluation data the system reached NDCG@10 of 0.91 and Precision@5 of 0.87, 34% above the keyword baseline.
Most inbound calls were the same few questions: what fits, what the specs are, whether it's in stock, and where to buy it. The assistant answers them on the website and in WhatsApp across 12 intents, including product recommendation, specification lookup, similar-product search, stock availability, cross-sell, a nearest-store locator across 1,075 partner points of sale, and handoff to a person. Intent classification holds at 93% accuracy under production load.
Similar-product search and cross-sell combine embeddings over the catalog with purchase history: alternatives are found by meaning, and add-ons by what customers actually buy together. Only about 5% of conversations needed a human, and inbound support calls halved within the first quarter.
Meals are cooked to order, but ingredients have to be bought in advance, so a bad guess turns into either waste or shortages. The system forecasts the daily number of containers for each of seven diet lines, one week ahead, using order history, seasonality, subscription trends, holidays, promotions, weather, and cancellations. Both gradient-boosting and LSTM models were built for the task.
The forecast feeds directly into the purchasing plan. Measured against the previous planning process under the same conditions, it reached a MAPE of 5.8% across diet lines and cut overproduction waste by about 22%.
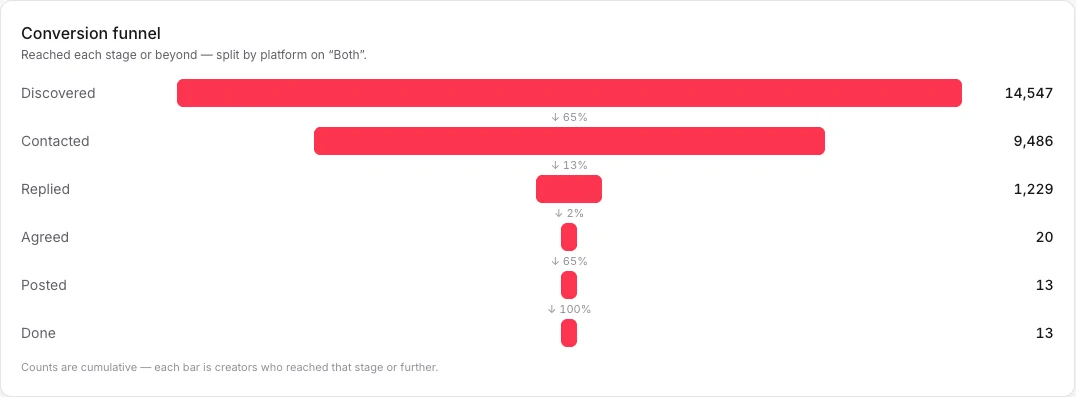
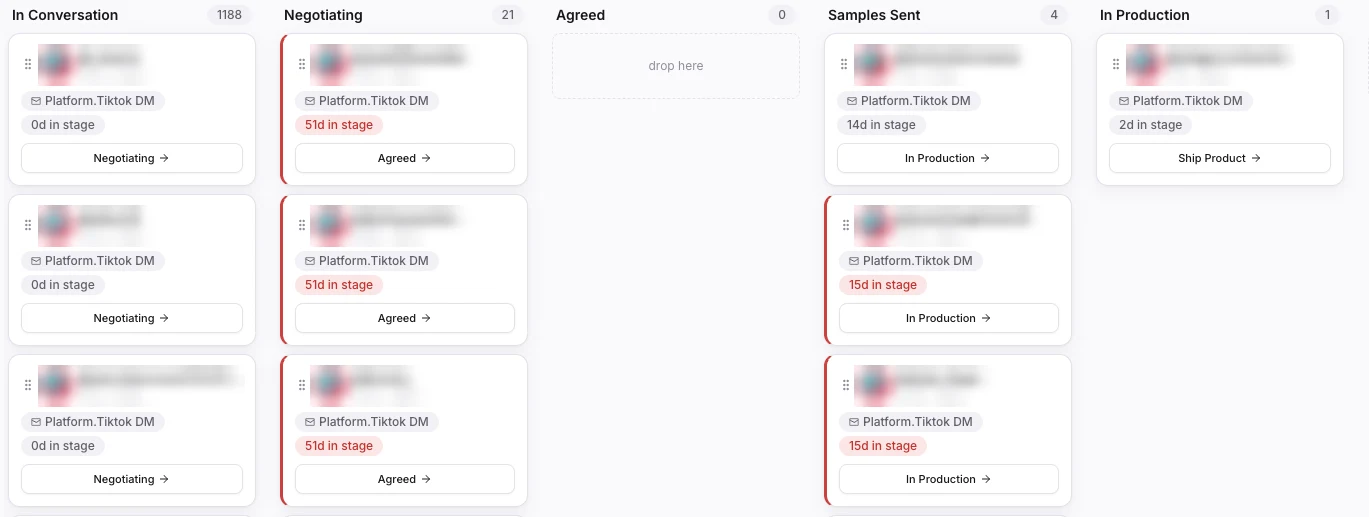
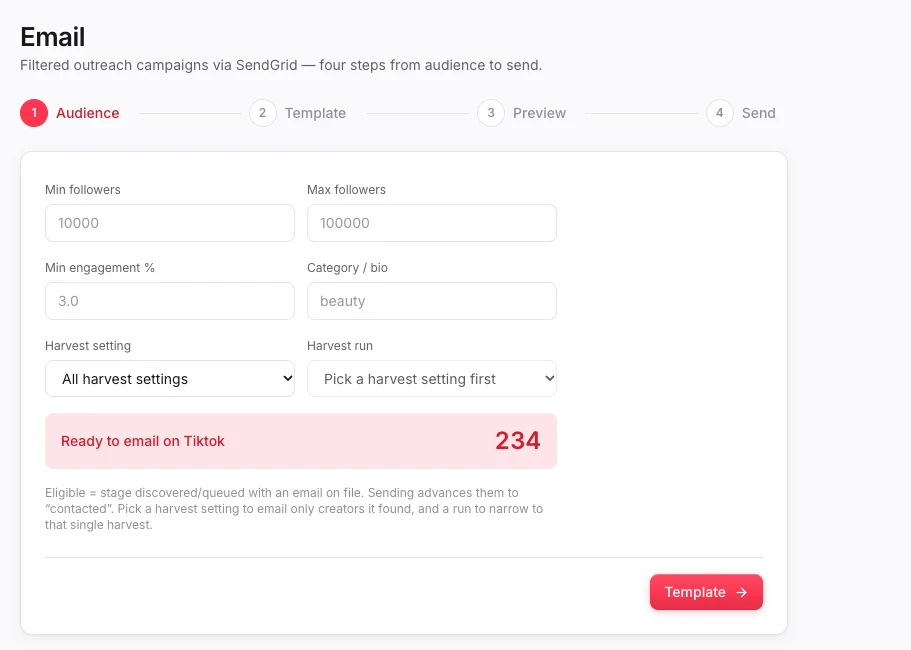
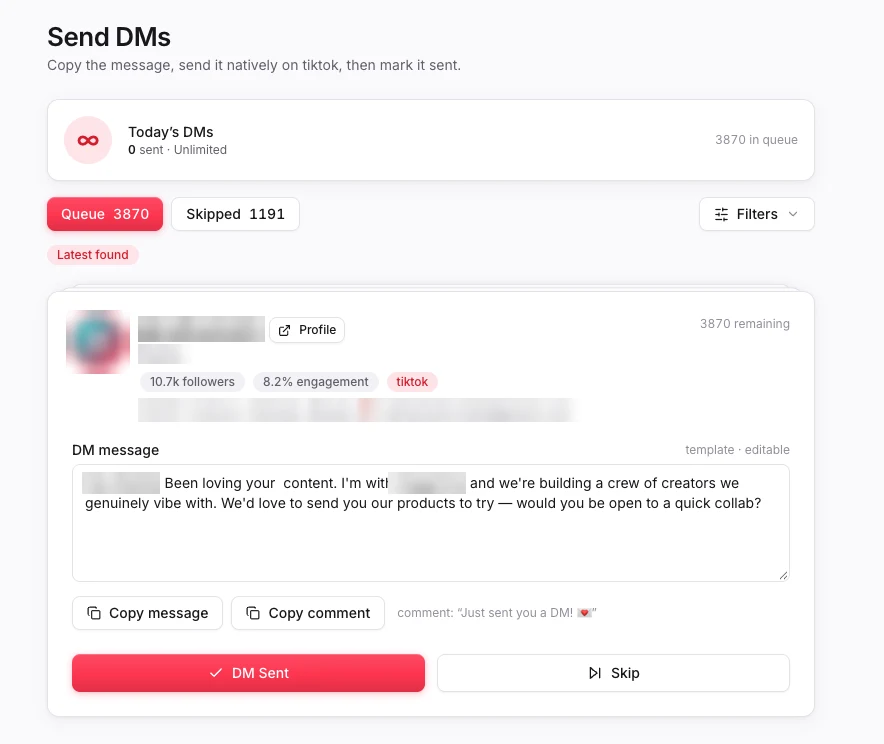
A single workspace for creator marketing on TikTok and Instagram, with a global toggle to work on one platform or both. Discovery runs on saved settings for follower range, engagement rate, and category or bio keywords, and every creator it finds lands in the pipeline. Outreach can go to a single creator, everyone matching a filter, or the results of a specific search run. Email campaigns go out through SendGrid in four steps: audience, template, preview, and send. TikTok DMs come from a queue with the message already prepared, so sending each one is a single action.
Every reply moves the creator onto a deal board with stages for conversation, negotiation, agreement, samples sent, in production, and posted. Deals that sit in one stage too long are flagged. Once a deal gets serious, the LLM drafts the parts that are personal: a contract and brief for each creator covering what to film, the terms, and the shipping address. It comes out as a downloadable document that the creator signs through a link. An analytics view tracks the funnel, channels, velocity, and cost.
Conversion funnel across both platformsDeal board, creator handles hiddenEmail campaign: audience by followers, engagement, and nicheDM queue with the prepared message, personal details hidden
Built in 2023, when a reliable domain assistant meant training your own model. The base is a T5 dialogue model, further pre-trained on the Russian Criminal Code to learn the language and structure of the law, then fine-tuned on a large set of real questions and answers from legal forums, with ChatGPT used to augment the training data.
Answers stream token by token, so a consultation feels like a live conversation and doesn't stall while a full response is generated. The firm still uses the system today.
The company had a large pool of customers who hadn't ordered in over a year and couldn't afford to contact all of them. The question was who gets a low-cost SMS and who gets one of the limited phone calls. The first version was a CatBoost purchase classifier on recency, spend, order count, contact outcomes, talk time, objections, answer rates, and profile data. Its overall ROC-AUC looked acceptable, but it was unstable at the top of the list, and the top of the list is the only part operators actually use.
I reframed it as a ranking problem under a fixed outreach budget. The purchase-only label treated a message that was never delivered, an explicit refusal, and an engaged non-buyer as the same negative. I replaced it with a graded response signal: reached, responded, engaged, interested, purchased. Class imbalance was handled in training through weighting and controlled negative sampling, while the evaluation set kept the natural production mix. Evaluation moved to the metrics behind the decision: top-K precision, lift over random, PR-AUC, revenue per 1,000 contacts, and cost per recovered order. All features are computed as of the scoring date, and validation respects time, so nothing from after the decision leaks into it.
CatBoostLearning to rankGraded response labelsClass imbalanceTop-K evaluationLeakage-safe validation
~10×
less time than a person doing the same work
Up to 10
campaigns a month, with no in-house paid-search staff
1 step
left to the human: approve and launch
Research starts outside Google. The agent reads Reddit discussions to learn what the target audience cares about and how they phrase it, and turns that into candidate keywords and themes. It then queries the Google Ads API for search interest and bid costs, so it can weigh how large and how expensive each audience is, and picks the segment that best fits the product. The result is a fully prepared campaign. A person only approves it, and the campaign is created.
After launch, a separate tracking platform takes over. The agent watches search keywords, negative keywords, and performance metrics, and proposes what to add or remove. Nothing changes without a human in the loop. The client runs up to ten campaigns a month and had no one to manage paid search. The agent does the work in roughly a tenth of the time a person would need, and the approach scales as the number of campaigns grows.
International Journal of Advanced Artificial Intelligence Research · Vol. 3, No. 7, pp. 69–81 · July 2026 · Sole author
When AI voice bots qualify customers before handing them to human operators, dialing too fast strands callers on hold and dialing too slowly leaves operators idle. The paper replaces fixed dialing settings with a receding-horizon integer-programming controller that models transfer delay as an empirical lag convolution — capturing most of the throughput of aggressive dialing while cutting abandonment and hold times. It is the method behind the predictive calling system above.
Designing Conversational AI Scripts for Emotional Engagement and Customer Readiness Detection in Sales Calls
2025
Balancing Automation and Human Intervention in Early-Stage Sales Calls
2024
Trustworthy AI for Conversational Customer Service Systems
2024
Automated Evaluation of Sales Calls Using Conversational AI
These four papers are being reissued with a new publisher over the next one to two months. Direct links will be added here as each becomes available again — happy to send copies in the meantime.
Research projects
2025
LLM knowledge gaps in low-resource programming languages
Supervised faculty research, Northeastern University
Why models that write reliable Python break down on Julia, and which intervention actually closes the gap — domain fine-tuning, RAG over language documentation, or in-context library injection.
2024
Adversarial attacks on code-generation models
Northeastern University
Black-box attacks against StarCoder and Code LLaMA using prompt injection and crafted prefixes, evaluating how fill-in-the-middle completion can be steered toward vulnerable code.
How I work
Six stages, in order
1
Discover
Learn how the business actually runs today — the process, the people, the data, and where the friction really sits.
2
Design
Choose the opportunity worth pursuing, define success metrics, and design the system and the operating model around it.
3
Build
Develop models, agents, and pipelines against real data, with evaluation in place from the first version.
4
Integrate
Connect the system to the tools people already use — telephony, CRM, databases, internal interfaces.
5
Measure
Compare against the baseline honestly: backtesting, counterfactual replay, human review, and cost per outcome.
6
Improve
Feed results back in. Recalibrate, extend coverage, and remove the failure modes that surface in production.
Technical depth
Under the hood
For the engineers in the room.
LLMs & AI agents
Tool use & function callingMulti-agent workflowsConversational systemsPrompt & model orchestrationMemory and business context